
How Fast Should Downtime Alerts Reach Your Team? A Practical Guide for Small Teams
Wondering how quickly you'll know when your site goes down? Learn how check intervals, multi-region verification and alert channels combine to set you
How Fast Should Downtime Alerts Reach Your Team?
For most startups and small businesses, a sensible target is for a critical outage to trigger a notification within about one to three minutes of starting. That's a target for notification. It doesn't promise that someone has seen the alert, and it certainly doesn't mean the problem is fixed. Whether you hit it depends on three things you control: how often you check (the check interval), how you confirm a failure is real (verification), and how the alert is delivered (the channel).
Here's the short version. Check critical things every minute, verify failures from more than one location, and send alerts to a channel a human will actually notice. Then test the whole chain on the real phones and accounts your team uses, because the timings in this guide are illustrative and vary by tool and setup. The rest of this post explains why, and how to do it without an enterprise budget or a dedicated DevOps person. ☕
Downtime Alert Response Time: Four Timings People Mix Up
Before we go further, let me pin down some terms. I've seen teams talk past each other because 'response time' can mean four different things:
- Time to detect: how long until a monitor notices something is wrong. Your check interval mostly drives this.
- Time to notify: how long until an alert actually reaches your team. This adds verification and delivery.
- Time to acknowledge: how long until a human says 'I've got this'. This is where people, phones and time zones come in.
- Time to resolve: how long until the problem is fixed. That depends on the issue, not the monitoring.
The one-to-three-minute figure above covers the first two. Acknowledgement and resolution need their own targets, and we'll set those later in the guide.
Why Alert Speed Matters (and When It Really Doesn't)
Picture a small online shop owner, let's call her Priya. She sells handmade candles, and a Friday afternoon deploy quietly breaks the checkout button. Nothing crashes. The homepage loads fine, so a basic uptime check would stay green. Priya finds out at 6pm when a customer emails: 'Is your site broken? I've tried three times.' By then the checkout has been dead for about three hours, and she has no idea how many people gave up without writing to anyone.
That's what slow detection costs, and it's rarely just one thing:
- Lost sales while customers can't pay, log in or reach your API
- Support tickets piling up for something you didn't know about
- Damaged trust, because people remember the shop that broke during their order
- Possible search visibility effects if outages are prolonged or keep recurring. A brief blip is unlikely to matter much, but persistent or repeated errors can cause search engines to crawl your site less or reconsider pages
Priya's story also shows a limit worth knowing about. A simple HTTP check tells you a page responds. It doesn't tell you a customer can complete a purchase. For revenue-critical journeys like checkout or login, you want a functional check (sometimes called a synthetic transaction), which walks through the steps the way a customer would. A keyword check that confirms the right content appears is a lighter alternative. Support for this varies between tools, so see what yours offers.
But I want to be honest with you: not everything needs a 30-second alert. A hobby blog that's down for ten minutes on a Sunday is an annoyance. A payment API that's down for ten minutes is a very different story. Google's SRE guidance makes a similar point: there's no universal ideal alert time. It depends on how much users are affected and how long you have before that impact becomes serious. It also suggests paging people for symptoms users actually feel, like errors or slowness, rather than every suspected cause.
A bit of perspective on the numbers: a service that's available 99.9% of the time still has an allowance of about 8 hours 46 minutes of downtime a year. At 99.99%, that drops to roughly 52 minutes. Those aren't alerting targets, but they show why the urgency of your alerts should match what your business can afford to lose.
So here's the idea I want you to hold onto. The time between 'something breaks' and 'someone is working on it' is:
detection time + verification time + delivery time + human acknowledgement time
You can tune each piece, and none of them needs anything fancy.
How a Downtime Alert Moves From Outage to Notification
Let's walk through what actually happens between 'something breaks' and 'someone fixes it'.
- Something breaks. A server crashes, a certificate expires, or a failed deploy takes down a page. The clock starts here, even though nobody knows yet.
- The next scheduled check fails. This is your detection delay. It depends on your check interval and on where in the cycle the outage happened to land.
- The failure is verified. Depending on your tool, other locations re-check before an alert is raised. This is your verification delay.
- The alert is sent, to Slack, email, Telegram, Discord or a webhook. This is your delivery delay.
- A human sees it and acknowledges it. This is your acknowledgement delay, and it's the one that varies most.
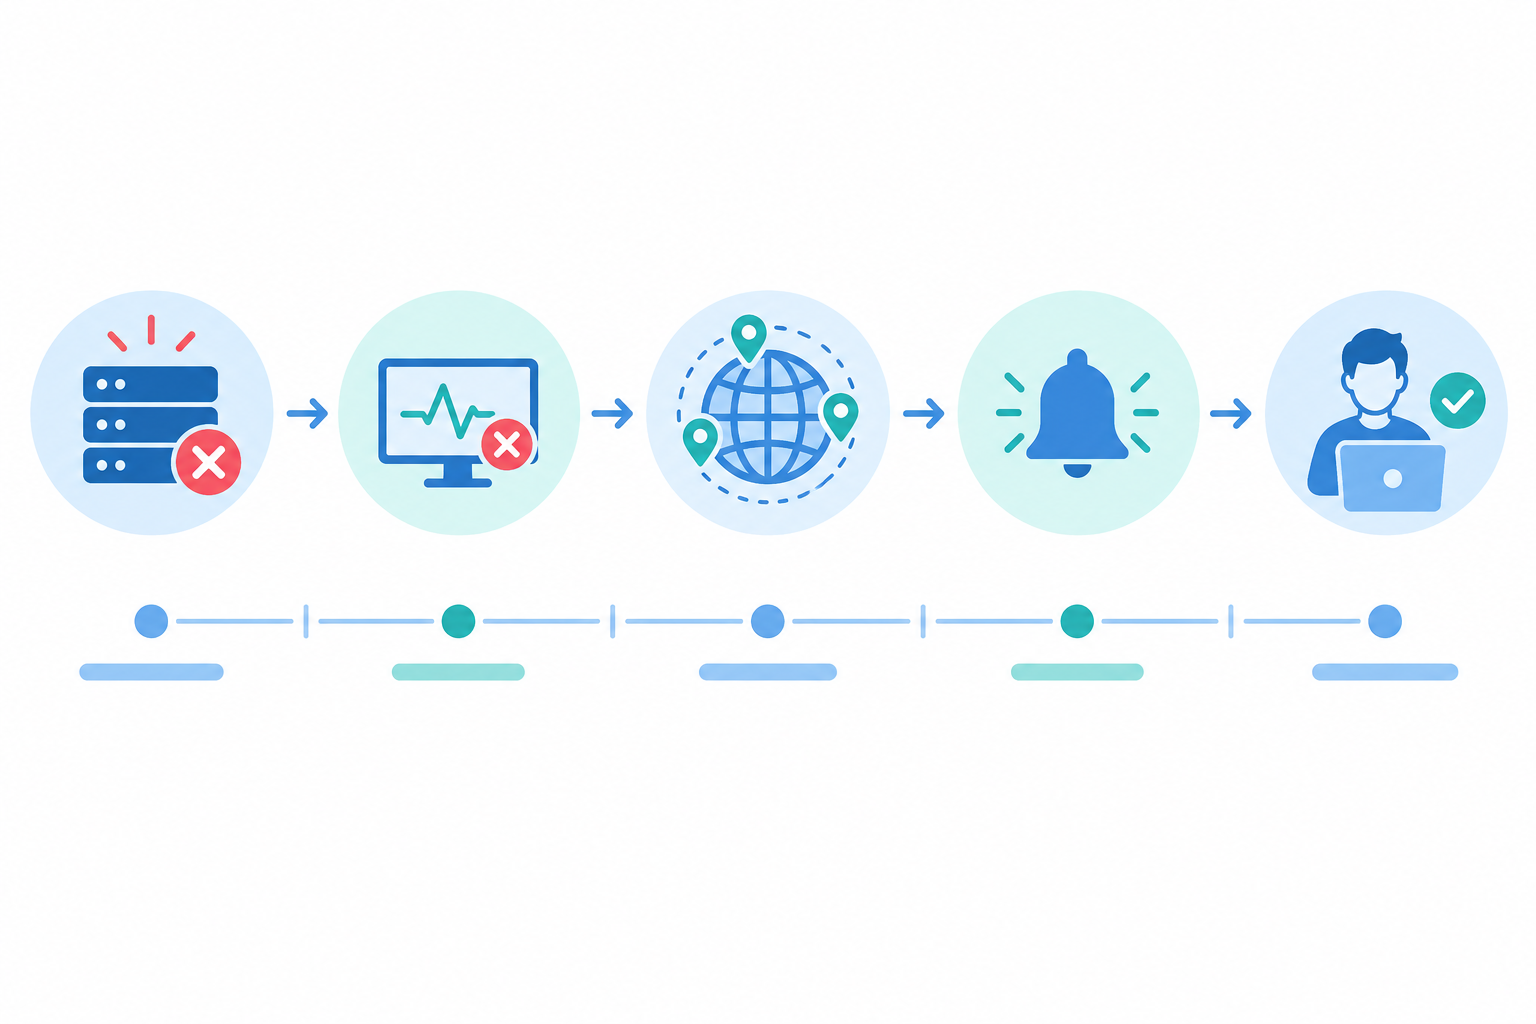
A worked example: how long does a downtime alert take?
Let's use a hypothetical setup. You check your checkout flow every minute. When a check fails, two other regions re-check in parallel, and an alert is raised if at least two of the three locations agree.
On average, an outage is spotted about 30 seconds after it starts, and in the worst case just under a minute. Under those assumptions, verification might add anywhere from a few seconds to around 30 seconds. Delivery to your phone might add a few seconds to a minute or so, depending on the channel and your phone's settings. That puts notification at roughly one to two minutes from breakage. Treat that as an illustration, not a guarantee. If your tool retries sequentially, waits for every location, or requires several consecutive failures, the number will be longer.
Then comes the human step. Maybe your phone is on the kitchen counter. Maybe it's 2am. In my experience this is often the slowest link in the chain, and the cheapest one to improve, which is why the goal-setting section below gives it its own target.
How Check Intervals Affect Downtime Detection Time
The check interval sets your worst-case detection delay. If you check every 5 minutes, an outage that starts just after a check can go unnoticed for almost 5 minutes. On average the delay is about half the interval: roughly 30 seconds for 1-minute checks, and around 2.5 minutes for 5-minute checks.
Those averages assume outages start at random points between checks and that checks run on schedule. In real life, retries, scheduling jitter and the odd probe failure can shift things, and the figures leave out verification and delivery time.
Does a shorter check interval mean faster alerts?
For detection, yes. For the whole chain, only if verification and delivery are also quick. Cutting your interval from 5 minutes to 1 minute is brilliant, but if the alert then goes to an email inbox nobody checks overnight, you've saved four minutes and lost four hours.
Very short intervals come with trade-offs too:
- More noise, since frequent checks are more likely to catch brief blips that fix themselves.
- More false positives, unless you have verification in place.
- Sometimes higher plan costs, because faster checks can use more resources.
Sensible downtime monitoring intervals for small teams
You don't need to agonise over this. Here's a simple rule of thumb:
- Use 1-minute checks for checkout, login and core APIs, anywhere a few minutes of downtime costs you money or customers.
- Add a functional check on top for revenue-critical journeys, so a 'page loads but checkout is broken' failure doesn't slip through.
- Use 5-minute checks for marketing pages, blogs and secondary sites.
Monitors that don't work on a check interval
Not everything is a 'ping it every minute' job. Heartbeat monitoring and cron job monitoring work the other way around. Your job pings Moonitor when it finishes, and you're alerted if the ping doesn't arrive within the expected window plus a grace period. That grace period, not an interval, decides how quickly you find out.
SSL certificate monitoring and DNS monitoring, meanwhile, are early-warning types. A certificate that expires in three weeks doesn't need a check every 60 seconds, and a daily or periodic check is plenty. Mixing intervals across monitor types lets you match urgency to importance instead of paying for speed you don't need.
Recommended Check Intervals by Monitor Type
Here's a practical cheat sheet. Please treat these as starting points, not rules. The right interval depends on how critical the service is, what your monitoring method and plan allow, and how costly a false alarm would be for your team.
| Monitor type | What it protects | Suggested interval / timing | Why |
|---|---|---|---|
| Website monitoring (HTTP/S) | Your main site and key pages | 1 minute for revenue pages; 5 minutes for others | Confirms a page responds, so customers' outages are noticed quickly |
| Functional / transaction check | Checkout, login and other multi-step journeys | 1-5 minutes, if your tool supports it | A page can return a successful response while the journey behind it is broken |
| API monitoring | Apps, integrations, mobile backends | 1 minute | One failing endpoint can break many things at once |
| Keyword monitoring | Pages that load but show the wrong content | 1-5 minutes | Checks that expected text appears, catching errors that return a 200 status but display a broken page |
| Server monitoring (port and ping) | Servers, databases, mail and other services | 1 minute for production; 5 minutes for internal tools | Infrastructure failures cascade quickly |
| Cron job and heartbeat monitoring | Backups, billing runs, scheduled reports | Match the job's schedule plus a sensible grace period | Alerts depend on missing pings, not on polling |
| SSL and domain expiry | Certificates and domain registrations | Daily or periodic checks, with early warnings | Hours or days are fine, as long as you get plenty of notice |
| DNS record change detection | Unexpected edits to your DNS records | Every few minutes to hourly | Changes can signal mistakes or tampering, but rarely need a 3am wake-up |
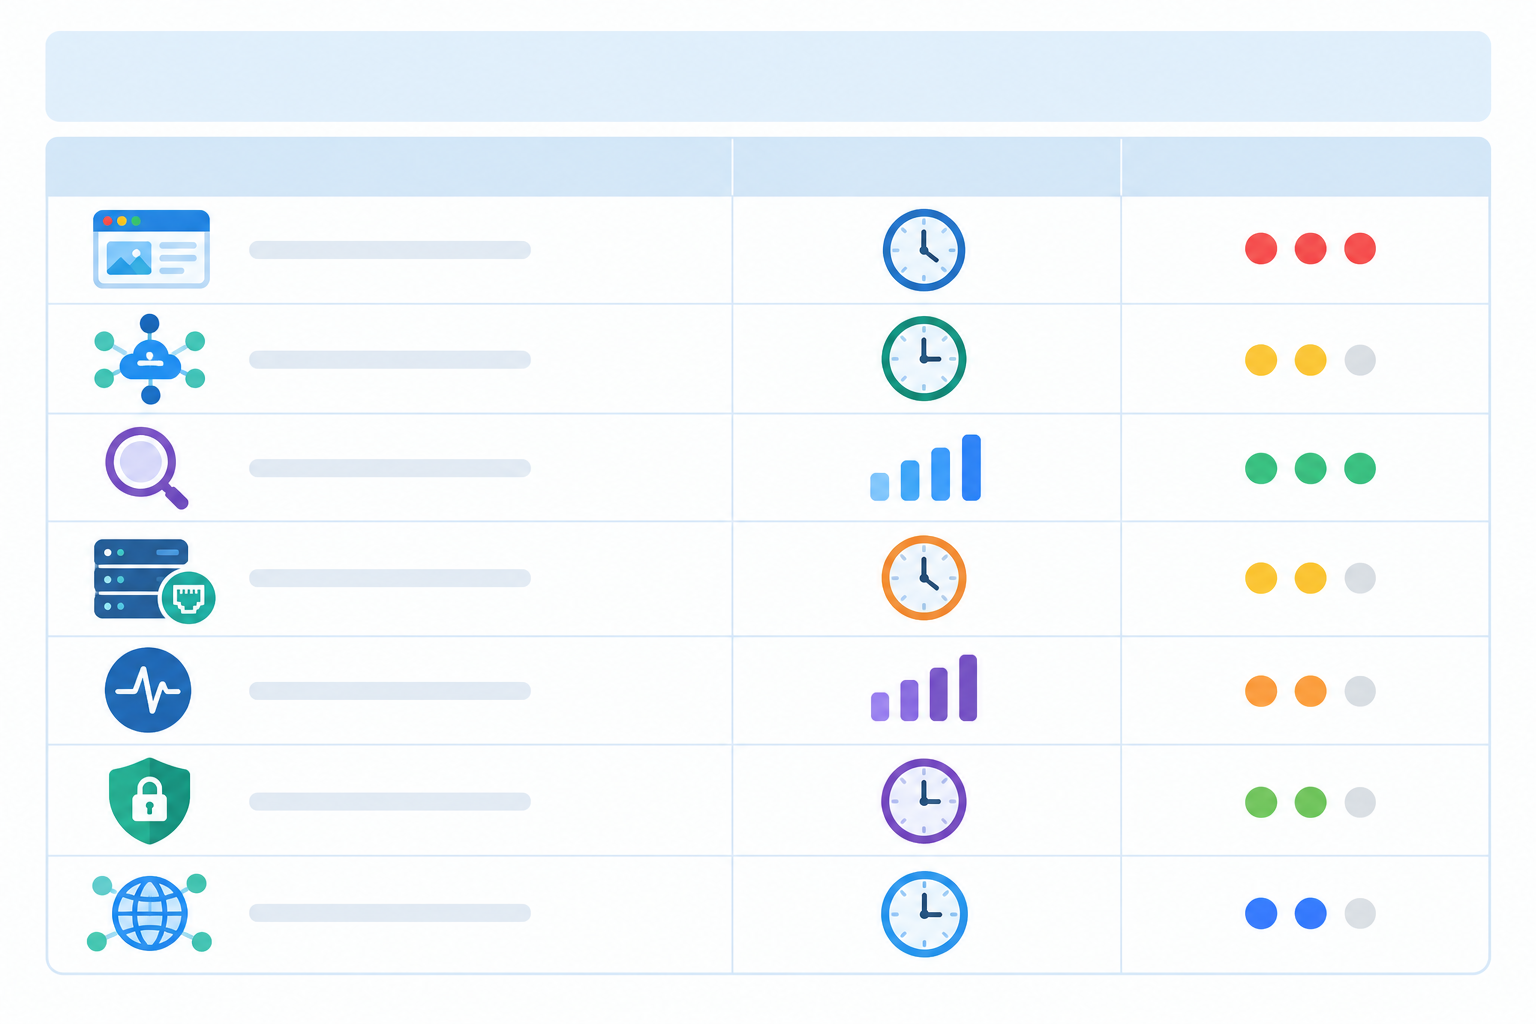
The split to remember is between time-critical monitors (website, API, server, and often cron jobs that feed customer-facing work) and early-warning monitors (SSL, domain expiry and most DNS changes), where acting within hours or days is perfectly fine.
The Role of Multi-Region Verification: Does It Slow Alerts Down?
A single failed check isn't always a real outage. Networks have hiccups and routes get congested. A one-off timeout from one location might mean your site is fine and the path between that probe and your server was briefly unhappy.
Multi-region failure verification handles this by re-checking from other locations before raising the alarm. It's a bit like making sure the front door is actually unlocked before you call the police. One quick look from a different angle saves a lot of embarrassment.
So, does verification slow downtime alerts?
A little, yes, but how much depends on how your provider runs it. Rechecking several regions in parallel and alerting once enough of them agree (a quorum rule) usually adds seconds. Retrying one location after another, or waiting for every location to report, can add much more. Before you trust any headline number, check these in your tool's settings:
- How many locations re-check a failure
- Whether they run in parallel or one after another
- How many must agree before an alert is sent
In return for that small delay, you lose the false alarms that teach teams to ignore their phones.
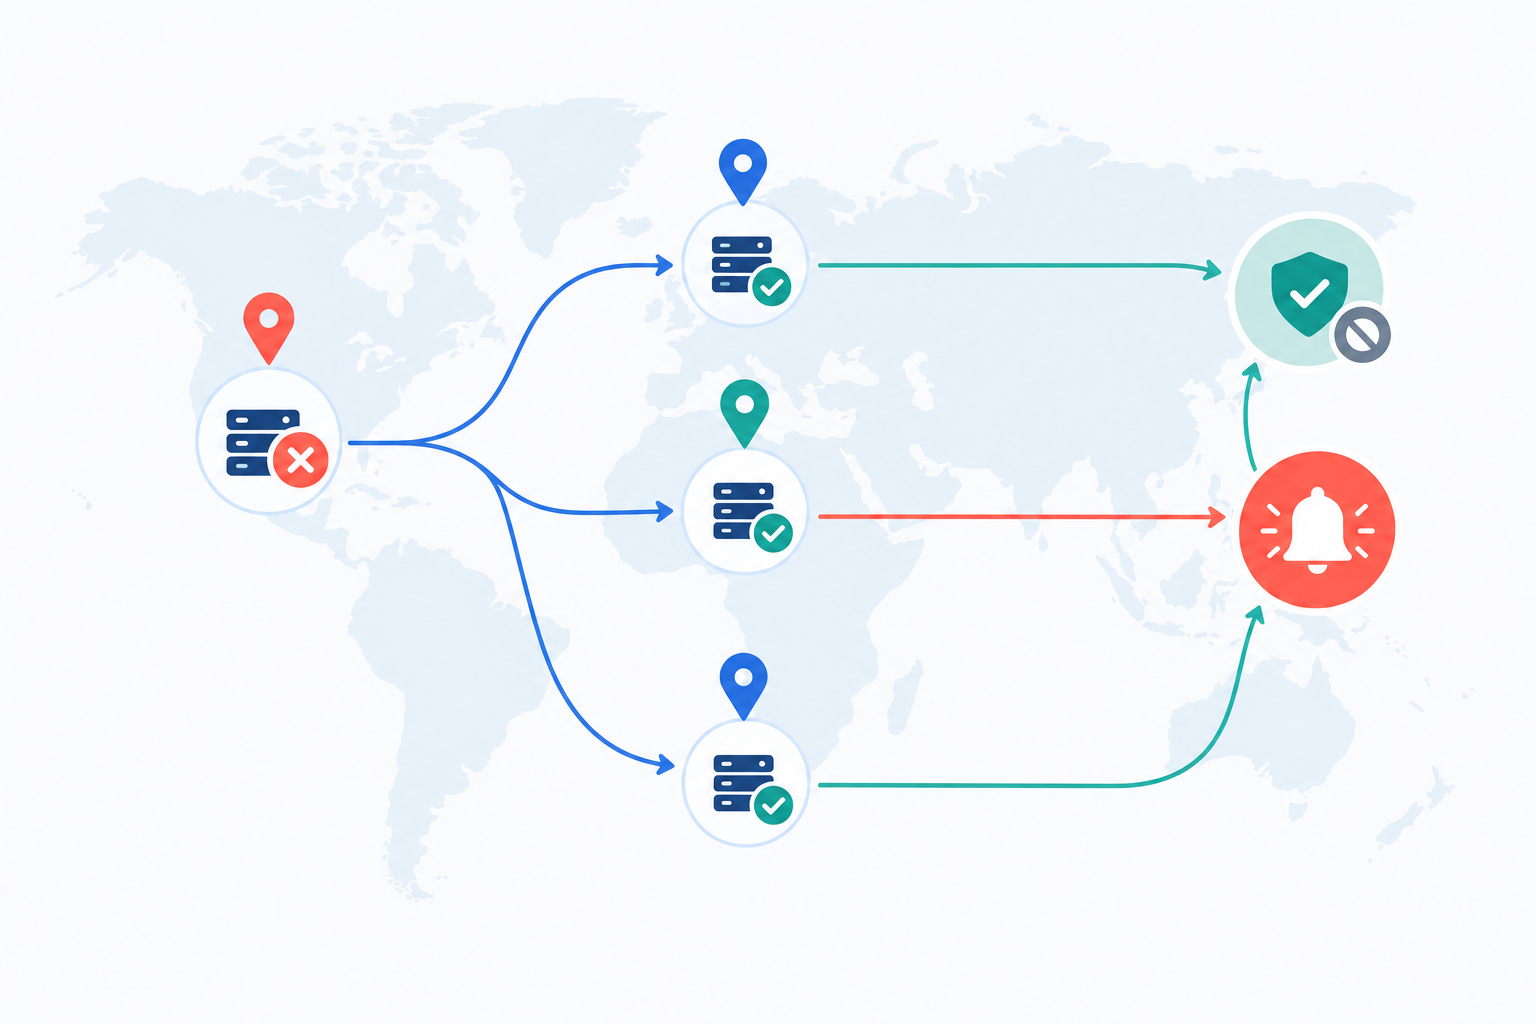
There's a useful side effect, too. If one region fails and the others succeed, that suggests a local routing issue. If several independent regions fail, you have much stronger evidence that your service is genuinely down.
Why false alarms are so costly
Alert fatigue is real. A team that gets three false alarms a week will, understandably, be slower to react to the fourth one, which might be real. Trust in your alerts is part of how fast you respond.
It's also what makes shorter intervals practical. When failures are verified, you can check every minute without drowning in noise. I keep coming back to this combination: frequent checks plus verification beats either one on its own.
Choosing the Right Alert Channel for Critical Outages
Here's something that surprises people: the alert itself usually leaves the system within seconds on every channel. But 'sent' isn't 'seen'. Email filtering, phone settings like Do Not Disturb or battery saving, patchy mobile signal and a misconfigured integration can all slow delivery. So the real question isn't 'which is fastest?' but 'which one will a human notice fastest?'
Here's how I'd think about each option:
- Slack and Discord work well during working hours and give the team visibility. Everyone sees the incident, and the conversation happens in one place. They're also easily buried or muted overnight.
- Telegram sends push notifications that tend to get noticed quickly on mobile. It's handy for solo founders and whoever is on call, provided notifications aren't silenced.
- Email is reliable and gives you a paper trail, but it's usually the slowest to be noticed. Use it as a backup, not your only line of defence.
- Webhooks are ideal for triggering automations, on-call tools, SMS gateways or phone call services when something is truly an emergency.
What's the fastest alert channel for critical outages?
Rather than picking just one, I'd suggest layering them:
- A channel for the whole team, like a Slack or Discord alerts channel, for shared visibility.
- A personal channel for the on-call person, such as Telegram on their phone.
- An escalation route for critical monitors, such as a webhook that sends an SMS or phone call if nobody has responded.
Then send a test alert to the actual devices and accounts your on-call person uses, at an awkward time of day. You'll learn quickly whether the phone is on silent.
If you're a UK-based team with no overnight staff, think honestly about out-of-hours cover. Who sees an alert at 11pm on a Saturday, on a bank holiday Monday, or during a Black Friday sales weekend? If the answer is 'nobody', better to find that out now than at the first big outage. Agree what's worth waking someone for, and keep everything else for the morning.
Setting Realistic Downtime Alert and Acknowledgement Targets
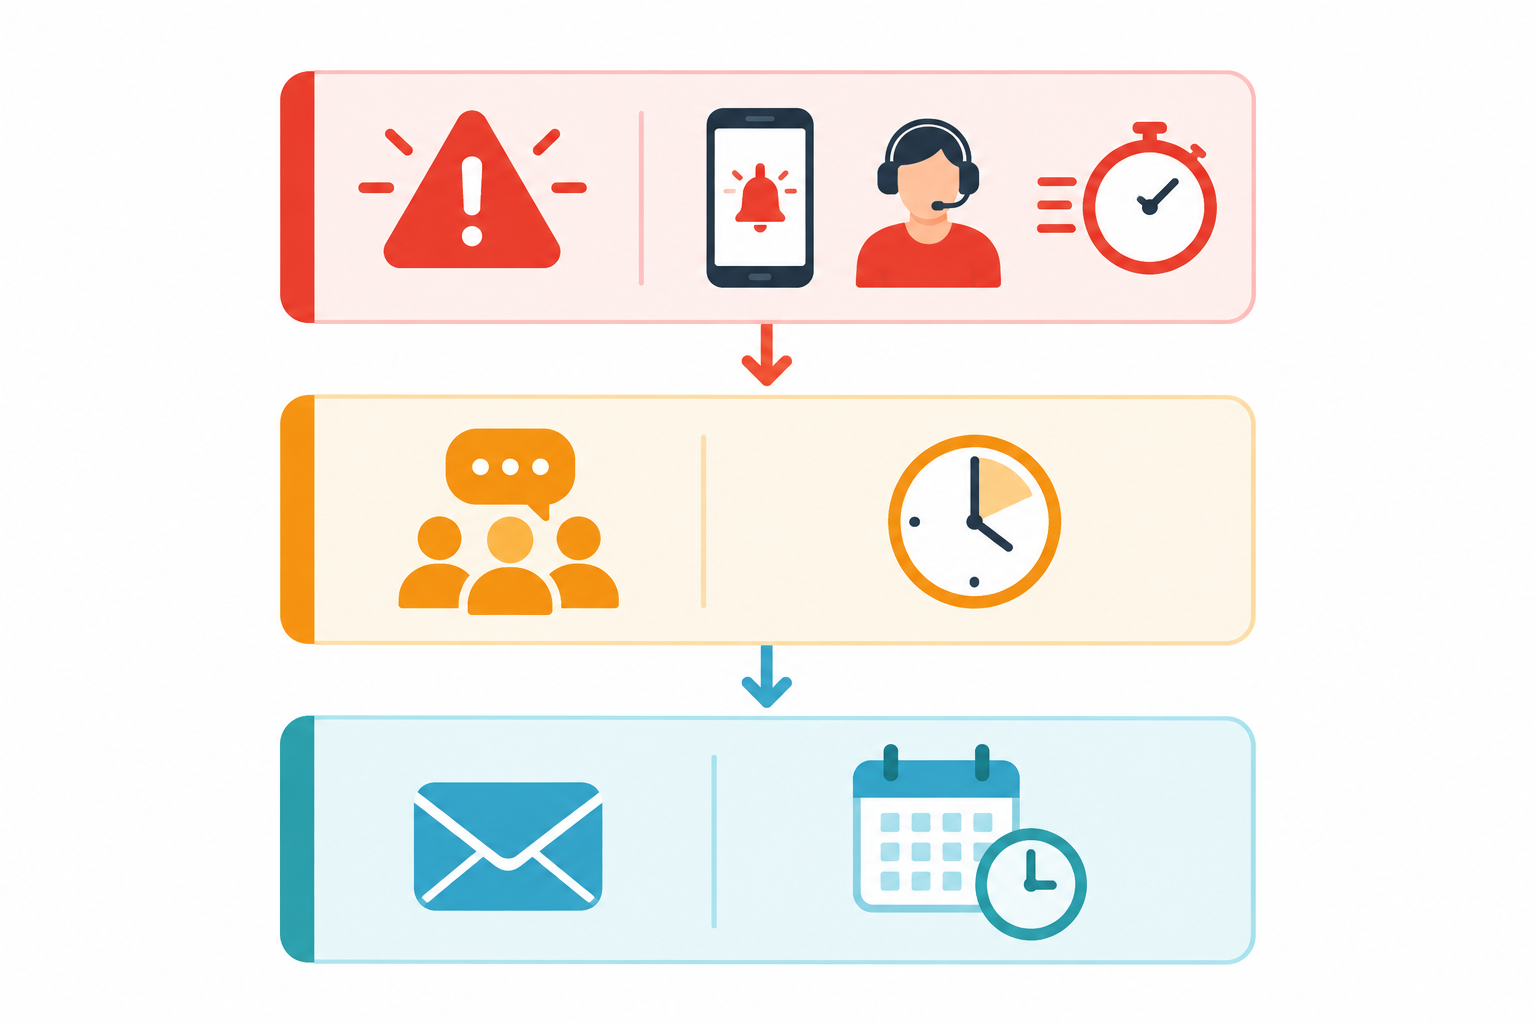
You don't need a formal incident process to get this right. Here's a simple six-step approach that works even for a team of two. The trick is setting two separate targets for each tier: how fast the alert should be delivered, and how fast a person should acknowledge it.
- List your critical systems (checkout, login, API, scheduled jobs) and rank them by how much an hour of downtime would hurt.
- Assign tiers. For example:
- Tier 1: notify within 1-3 minutes, with a named person acknowledging within about 5-15 minutes during agreed cover hours
- Tier 2: notify within 5-10 minutes via the team channel, acknowledge within the working day or within an hour in office hours
- Tier 3: notify within hours by email, review the next working day
- Match intervals and channels to each tier. Tier 1 gets 1-minute checks (plus a functional check for revenue journeys) and a personal mobile alert. Tier 3 gets periodic checks and an email.
- Decide who is on call and what happens if they don't respond. Even in a team of two, agree who's first, who's backup and how long to wait before escalating, say 10 minutes with no acknowledgement.
- Test the whole chain. Trigger a test failure and time when the alert arrives, when someone notices, and when someone acknowledges. Most teams skip this step, and it's the most revealing.
- Review monthly. Look at your incident history and response-time analytics, then adjust. Maybe a Tier 2 monitor deserves a promotion, or a noisy one needs a calmer setup.
These numbers are starting points. A two-person team can't realistically promise a 5-minute acknowledgement at 3am, and it's better to set a target you'll meet than one you'll quietly ignore.
One more tip: a public status page takes a lot of pressure off during an incident. When customers can see 'we know about it and we're on it', they're far less likely to flood your support inbox, which frees you up to actually fix things.
A Practical Example With Moonitor
Everything above applies whichever tool you use. As one example, here's what we built Moonitor to do. It verifies failures from multiple regions and sends alerts to Slack, Discord, Telegram, email and webhooks. One dashboard covers website, API, server, cron job, SSL certificate and DNS monitoring, along with status pages and incident history.
At the time of writing, the Solo plan starts at $14/mo for 20 monitors, the Max plan is $49/mo for unlimited monitors, and there's a 7-day free trial with no credit card needed. Prices are in US dollars, so UK teams should expect exchange rates and possibly VAT to apply. Please check our pricing page for current details before you decide.
Whichever tool you pick, my gentle suggestion is to use the trial to test your alert chain properly. Set up a monitor, trigger a failure, and time how long it takes for the right person to notice. That one test will tell you more about your real timings than any setting ever could.
Frequently Asked Questions About Downtime Alert Speed
How quickly will I know if my site goes down?
With a 1-minute interval and multi-region verification, a notification within roughly one to three minutes is a reasonable target, though your provider's verification settings and your channel affect the real figure. With a 5-minute interval, the worst case for detection alone is nearly five minutes. How soon someone acts is a separate question, and it depends on who's on call.
Does a shorter check interval mean faster alerts?
It means faster detection, not necessarily a faster response. If verification is slow, the channel is easy to miss or nobody is on call, the extra speed is wasted. See the timings section above for how the pieces add up.
What's the fastest alert channel for critical outages?
There isn't a single winner, because the question is which channel gets noticed quickest. For many small teams that's a mobile push, such as Telegram, backed by a webhook that triggers a call or SMS for critical systems. Email works best as a backup. Test on your real devices.
How does verification affect alert speed?
It adds some delay, from seconds to longer, depending on whether checks run in parallel, how many locations must agree, and your provider's retry policy. The payoff is far fewer false alarms, so the alerts you do get are ones you can trust.
Do I need 1-minute checks on every monitor?
No. Save the shortest intervals for revenue-critical or customer-facing systems like checkout, login and core APIs. Less urgent pages can use 5-minute checks, and SSL or domain expiry monitors only need periodic checks.
How do I know if a cron job has failed?
Heartbeat monitoring works the other way around from a normal check. Your job pings Moonitor when it finishes, and if the ping doesn't arrive within the expected window plus a grace period, you get an alert. Detection speed depends on that grace period rather than a check interval.